 Hugging Face
 X (Twitter)
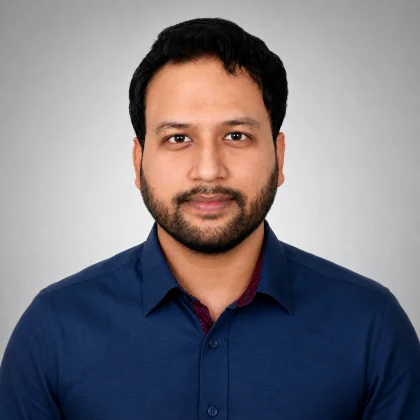
Mir Tafseer Nayeem
I study how human context shapes language models, their applications, and their evaluation.
People produce the language data that models learn from. Tokenization turns that data into units models use to predict what comes next. My research follows this path from who creates information to whom AI systems serve, and asks how we can evaluate the outcomes.
I am a final-year PhD Candidate in Computing Science at the University of Alberta, advised by Prof. Davood Rafiei.
Modeling
Whose language can a model learn to represent?
People of different ages, dialects, and languages produce the text models learn from, but tokenization and training do not support every name or variety equally. I develop data resources, algorithms, and training methods to understand and reduce those gaps.
- KidLMEMNLP 2024 Best Resource Paper
- English (US) as DefaultPreprint 2026
- NameTracePreprint 2026
- STRRNeurIPS 2025 Workshop
- Stop Taking Tokenizers for GrantedEACL 2026
Applications
How can AI applications better serve diverse people?
People create and use information in different ways, shaped by their experience, preferences, language, culture, and age. I use that context to select evidence, design outputs, and evaluate whether applications serve their intended audiences.
- OpinioRAGCOLM 2025
- CineSubBenchPreprint 2026
- Review HelpfulnessEACL 2023
- XL-HeadTagsACL 2024
- SurveyGenEMNLP 2025
Responsible Evaluation
What do benchmark scores miss about users and their contexts?
Benchmarks can hide whose data and judgments define success. I audit their source and target users, build multilingual evaluations of model judges, and test how country income and deceptive chart designs affect model outputs and users' interpretations.
- WhoseBenchPreprint 2026
- Fair NarrativesEMNLP 2025
- Chart DeceptionIEEE VIS 2025 Best Short Paper
- Lost in TranslationACL 2026
Announcements
-
One paper accepted at ACL 2026.
-
One paper accepted at EACL 2026.
-
ChartDeception received the Best Short Paper Award at IEEE VIS 2025.
-
KidLM received the Best Resource Paper Award at EMNLP 2024.
-
Three papers accepted at EMNLP 2025.
-
One paper accepted at COLM 2025.
-
One paper accepted at IEEE VIS 2025.
-
One paper accepted at ACL 2025 Industry Track.
-
One paper accepted at NAACL 2025 Industry Track.
-
Two papers accepted at EMNLP 2024.
-
One paper accepted at ACL 2024.
-
One paper accepted at LREC-COLING 2024.
-
One paper accepted at CIKM 2023.
-
Two papers accepted at EACL 2023.
-
Awarded the Huawei PhD Fellowship.
-
Started PhD in Computing Science at the University of Alberta.
-
One paper accepted at EACL 2021.
-
One paper accepted at AAAI 2021.
-
Our COLING paper received the Area Chair Favorite Paper Award.